

[CSPro 24] 登机牌条码
Background
The testdata on Luogu is only for non-official communication and is not official testdata. Official judging link: https://www.cspro.org/.
Xixiaifu Island has beautiful scenery and is crowded with tourists. However, because transportation to and from the outside world relies only on ferries, the inconvenience of transportation has seriously limited the development of the island’s tourism industry. After persistent effort, the Xixiaifu Island administrative committee secured an investment and built a general aviation airport. After three years of intensive construction of the main facilities, Xixiaifu Island General Aviation Airport has finally started installing and debugging the software and hardware systems inside the terminal building. Xiao C is a development engineer in the airport operating company’s IT department. Recently, an important task for the IT department is to develop a self-service boarding pass printing system. The following figure shows a boarding pass sample designed by the design department according to the industry standards of the International Civil Aviation Organization.
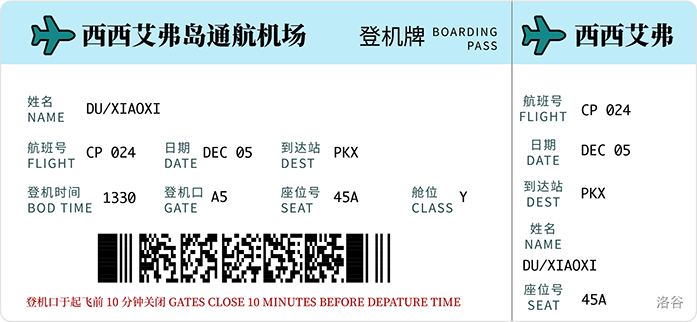
The most important part of the boarding pass is the machine-readable barcode at the very bottom. Xiao C is responsible for developing the algorithm to generate this machine-readable barcode. From the data to be encoded to the barcode, there are many steps in between. Xiao C asks you to help handle the data encoding part.
Problem Description
The barcode on the boarding pass is a PDF417 code. The structure of a PDF417 code is shown below.
:::align{center}
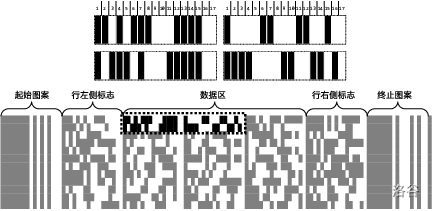 :::
The basic element of a PDF417 code is a Module. All modules are rectangles of the same size, filled with either black or white. Modules first form rows, and multiple rows are stacked to form the entire PDF417 code. In each row, every modules represent one Code word. A code word is the smallest data unit in PDF417 encoding. In each code word pattern, there are four black rectangles and four white rectangles arranged alternately, which is where “417” comes from. Each row begins and ends with fixed start and stop patterns. Adjacent to them are the left and right row indicators, which represent information such as the row number and the number of code words in the row. The middle part is the data area. The encoding process is: first, according to the encoding rules, convert the data to be encoded into code words; then compute error correction code words based on the chosen width of the PDF417 code (i.e., the number of code words per row) and the redundancy level; finally, convert the code words into corresponding patterns by rules, and fill them into the data area in order from left to right and from top to bottom, and combine them with the start/stop patterns and the left/right row indicators to form a complete PDF417 code.
Each code word is a number from to , and each code word can encode two input characters. For the input data to be encoded, encode it according to the table below. The encoder has three modes: uppercase letter mode, lowercase letter mode, and digit mode. At the beginning of encoding, the encoder is in uppercase letter mode. When the encoder is in a certain mode, it can only encode the corresponding type of characters. If you need to encode other types of characters, you must switch to the corresponding mode using special values. There can be multiple ways to switch modes. For example, to switch from uppercase mode to lowercase mode, you can switch directly using , or you can first switch to digit mode using and then immediately switch to lowercase mode using . You need to choose the shortest way to switch, so only the former method is correct. Note that from lowercase mode you cannot switch directly to uppercase mode; you must go through digit mode as a transition.
| Value | Uppercase Mode | Lowercase Mode | Digit Mode |
|---|---|---|---|
| A | a | ||
| B | b | ||
| C | c | ||
| D | d | ||
| E | e | ||
| F | f | ||
| G | g | ||
| H | h | ||
| I | i | ||
| J | j | ||
| K | k | ||
| L | l | ||
| M | m | ||
| N | n | ||
| O | o | ||
| P | p | ||
| Q | q | ||
| R | r | ||
| S | s | ||
| T | t | ||
| U | u | ||
| V | v | ||
| W | w | ||
| X | x | ||
| Y | y | ||
| Z | z | ||
| Lowercase | |||
| Digit | Uppercase | ||
| Padding | |||
Using this method, you can obtain a sequence of numbers not exceeding . If there is an odd number of such numbers, append a at the end to make it an even number. Group them into pairs. Suppose and are two consecutive numbers in a pair, then the resulting code word is:
For example, to encode “”, first generate the number sequence according to the alphabet:
H E    1    l  o
7 4 28 1 27 11 14
Since there is an odd number of numbers, append at the end, and then group them into pairs:
(7, 4), (28, 1), (27, 11), (14, 29)
Finally compute the code words. For example, , and so on, obtaining the code words:
214, 841, 821, 449
Next, compute the error correction codes. The number of error correction code words is determined by the error correction level. Suppose the error correction level is , then the number of error correction code words is . In particular, if is specified, it means no error correction code words are needed. To compute error correction code words, first determine the data code words. The data code words are formed by concatenating the following data in order (as shown in the figure):
:::align{center}
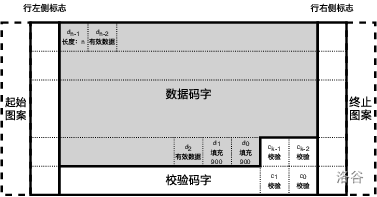 :::
- One length code word, representing the total number of data code words , including this length code word, the data code words, and the padding code words.
- Several data code words, which are the code word sequence computed above.
- Zero or more padding code words, each being a repeated , so that the total number of code words (including the error correction code words) is exactly divisible by the row width of the data area.
Let all data code words be in order, and the error correction code words be in order. Then the error correction code words are computed as follows:
Take the degree- polynomial , and the degree- polynomial $d(x) = d_{n-1}x^{n-1} + \dots + d_{n-2}x^{n-2} + \dots + d_1x + d_0$. Find a polynomial and a polynomial of degree not exceeding such that
$$\begin{aligned} x^k d(x) &\equiv q(x) g(x) - r(x) \end{aligned}$$Then, for each coefficient of the term in , take it modulo (take the positive value). The resulting number is the error correction code word .
For example, if you want to encode into a PDF417 barcode, and the row width of the data area is code words (i.e., modules), and the error correction level is . Then there are two error correction code words. From the previous encoding result, there are data code words. Adding one length code word gives code words in total. Therefore, you need to add one padding code word so that the total number of code words including the error correction code words can be divisible by . In this way, there are data code words used to compute the error correction code words:
6, 214, 841, 821, 449, 900
Therefore, , $d(x) = 6x^5 + 214x^4 + 841x^3 + 821x^2 + 449x + 900$. It is not hard to get , so we can compute:
$$\begin{aligned} c_1 &= 229 \equiv -32902164 \mod 929, \\ c_0 &= 811 \equiv 98246277 \mod 929. \end{aligned}$$Thus, the complete code word sequence is:
6, 214, 841, 821, 449, 900, 229, 811
In this problem, the task you need to help Xiao C complete is: given the data to be encoded, compute the code word sequence that needs to be filled into the data area. The processed data contains only uppercase letters, lowercase letters, and digits.
Input Format
Read input from standard input.
The first line contains two integers and separated by a space, representing the number of code words each row of the data area can hold and the error correction level. It is guaranteed that and . In particular, when , it means no error correction code words are needed.
The second line is a non-empty string containing only uppercase letters, lowercase letters, and digits. Its length guarantees that after encoding, the total number of data code words is less than .
Output Format
Write to standard output.
Output several lines, one number per line, representing the complete encoded code word sequence.
5 -1
HELLO
5
214
341
449
900
4 0
HE1lo
6
214
841
821
449
900
229
811
Hint
Explanation for Sample 1
The data to be encoded is HELLO. First, look it up in the table and map it to numbers. Note that since the encoder starts in uppercase letter mode, no extra mode switching is needed. Therefore the numbers are: . Since there is an odd number of numbers, append to form the sequence . Then group them into pairs and compute the code words: , and so on, getting . This input does not require generating error correction code words, and the width of the data area is code words. Currently there are data code words, and adding the length code word at the beginning gives code words. Therefore, one padding code word is needed so that the total number of code words reaches and fills one row. Note that the length in the length code word includes all data code words, so the length code word is rather than . Finally, the code word sequence is .
Explanation for Sample 2
This test case is the example previously used to illustrate the encoding process.
Subtasks
For of the data, , and the input string contains only uppercase letters or only lowercase letters.
For of the data, .
For of the data, .
For of the data, all input requirements are satisfied.
Translated by ChatGPT 5